AI
 5 MIN READ


Every enterprise is racing to adopt the most powerful AI model. GPT-4, Gemini, Claude, Llama. The debate never ends. But here is what most companies miss entirely: the model is not your competitive edge. The data pipeline feeding it is.
Think of an AI model as a high-performance engine. Without clean fuel, precise routing, and a reliable delivery system, even the most powerful engine stalls. The companies achieving transformational AI outcomes are not the ones with access to the best models. They are the ones who have built intelligent, governed, and scalable data pipelines that make those models actually work.
This blog breaks down why the data infrastructure layer above the model is where real enterprise value lives, what it takes to build it right, and why getting it wrong will silently destroy your AI ROI.
The Data Gap Most Enterprises Are Ignoring
Despite billions poured into AI initiatives, enterprise data readiness remains critically underdeveloped. According to a global study by Harvard Business Review Analytic Services in partnership with Cloudera (March 2026), only 7% of enterprises say their data is completely ready for AI adoption, while more than 27% admit their data is either not very or not at all ready. The same report found that siloed data and difficulty integrating sources were the top barriers, with 56% of respondents flagging them.
The irony? These organizations are simultaneously accelerating their AI initiatives. They are building on a foundation that cannot support the weight they are placing on it.
What Is an AI Data Pipeline and Why Does It Define AI Success?
An AI data pipeline is the end-to-end infrastructure that collects, cleans, transforms, routes, and delivers data to AI models for training, fine-tuning, and inference. It is not just an ETL process. A mature AI data pipeline includes:
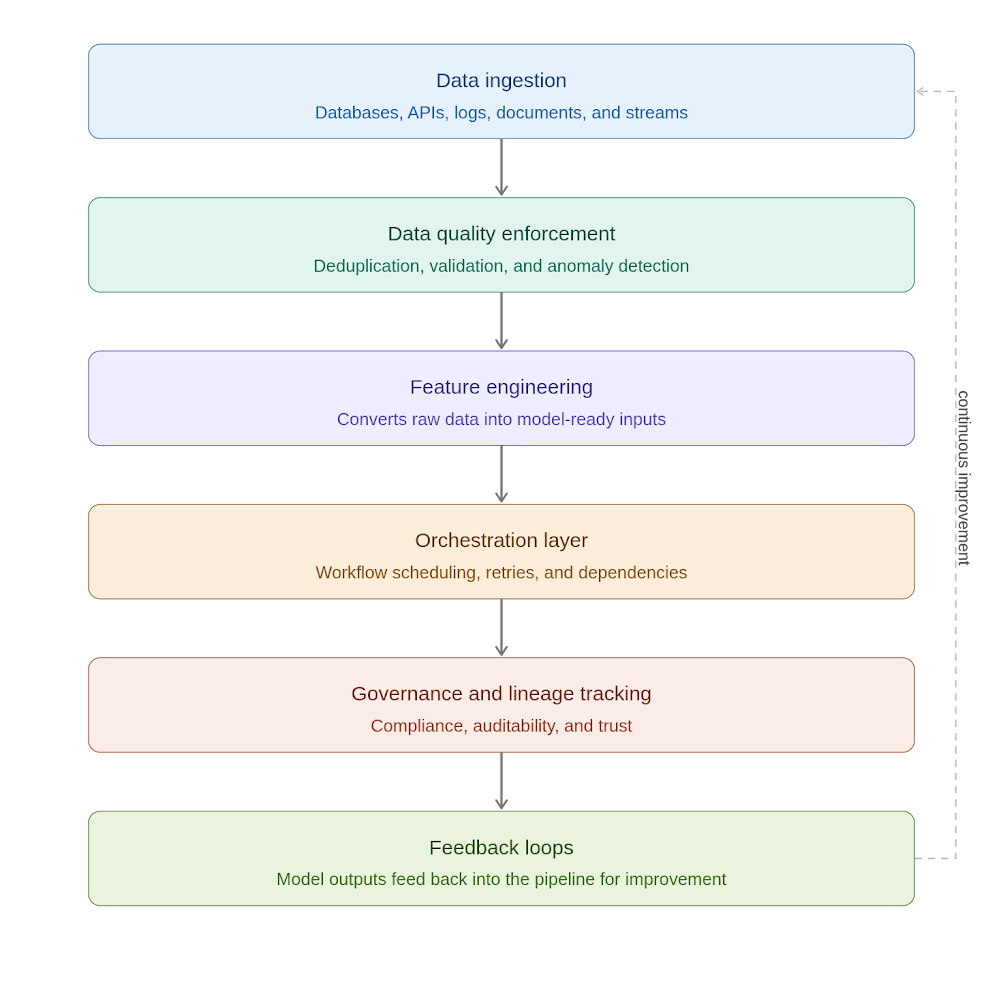
- Data ingestion from structured and unstructured sources (databases, APIs, logs, documents, streams)
- Data quality enforcement, including deduplication, validation, and anomaly detection
- Feature engineering that converts raw data into model-ready inputs
- Orchestration layers that manage workflow scheduling, retries, and dependencies
- Governance and lineage tracking to ensure compliance, auditability, and trust
- Feedback loops that bring model outputs back into the pipeline for continuous improvement
Without each of these components functioning together, the AI model receives inconsistent inputs and produces inconsistent outputs. This is the root cause of most enterprise AI failure, not the model’s intelligence. For enterprises at the frontier of AI maturity, agentic AI consulting can help design systems where model outputs autonomously trigger downstream actions within the same pipeline ecosystem.
The Real Competitive Moat: Why Data Infrastructure Wins
Models are increasingly commoditized. OpenAI, Anthropic, Google, and Meta are making frontier capabilities available to everyone. What they cannot give you is your proprietary data, your historical transaction records, your customer behavior patterns, or your domain-specific knowledge. That is yours alone.
The companies extracting the most value from AI are those that have turned their internal data into a structured, accessible, and continuously refreshed asset. Amazon’s recommendation engine is not powerful because it uses a better model. It is powerful because Amazon has built a data pipeline that captures every click, scroll, and purchase in real time and feeds it into models that can act on it within milliseconds.
The same principle applies at every scale. When a financial services firm processes loan applications with AI, the model is generic. The edge comes from the proprietary risk signals built into the training data and the pipeline architecture that keeps it current and clean.
The data pipeline is not infrastructure. It is a strategy.
Key Components That Separate High-Value Data Pipelines from Average Ones
Not all data pipelines are built equal. Here is what defines the ones that actually move the needle for AI outcomes:
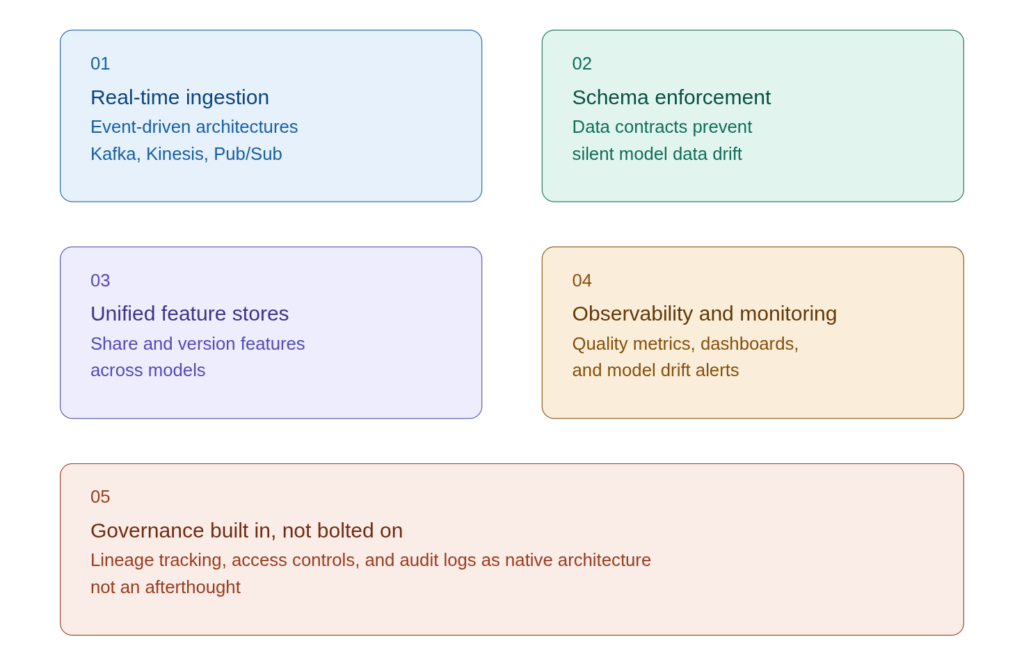
1. Real-Time or Near-Real-Time Ingestion
Static batch pipelines create lag between the world and your model. High-value pipelines use event-driven architectures such as Apache Kafka, AWS Kinesis, and Google Pub/Sub to keep data fresh and models relevant.
2. Schema Enforcement and Data Contracts
Teams that skip schema validation end up with AI models trained on inconsistent data. Data contracts between producers and consumers prevent silent data drift from corrupting model performance.
3. Unified Feature Stores
Feature stores like Feast or Tecton allow teams to share, reuse, and version features across models. Without them, data science teams repeatedly rebuild the same transformations, wasting time and introducing inconsistencies.
4. Observability and Monitoring
A pipeline with no observability is a black box. Data quality metrics, pipeline latency dashboards, and model drift alerts are non-negotiable for production AI systems that must remain reliable over time.
5. Governance Built In, Not Bolted On
Regulatory requirements around AI are intensifying globally. Pipelines that treat governance as an afterthought become compliance liabilities. Lineage tracking, access controls, and audit logs should be native to the architecture.
Real-World Use Cases: The Pipeline Advantage in Action
Healthcare: A hospital network deployed an AI model to detect sepsis early. Initial accuracy was poor, not because the model was weak, but because EHR data from three different systems was arriving in different formats with inconsistent timestamps. After rebuilding the ingestion and normalization layers, prediction accuracy improved significantly, and clinical adoption followed.
Retail: A global retailer running AI-driven demand forecasting found that its model was relying on week-old inventory data due to a batch pipeline bottleneck. Switching to a near-real-time pipeline reduced overstock costs and improved in-stock rates during peak season.
B2B SaaS: A software company building a churn prediction model found that model performance plateaued until they added behavioral telemetry data through a new pipeline. The additional features, not a better model, drove a measurable reduction in churn.
In each case, the decisive improvement came from the pipeline layer, not model switching.
How Ksolves Helps You Build the AI Data Infrastructure That Actually Delivers
Organizations often invest heavily in AI tools but underinvest in the foundational data architecture that determines whether those tools succeed or fail. As a trusted AI/ML services provider, Ksolves helps enterprises design, build, and scale intelligent data pipelines that bridge the gap between AI ambition and operational reality.
From real-time ingestion architectures and feature engineering frameworks to governance-ready data platforms and model feedback loops, Ksolves brings both the technical depth and business context to make your AI data infrastructure a lasting competitive advantage, not just a project.
Whether you are starting from scratch or modernizing a fragmented data stack, Ksolves – an AI-First Company works with your existing environment to deliver production-grade, compliant pipelines built to scale.
Conclusion
The AI model is not your moat. Your data pipeline is. In a landscape where model access is increasingly democratized, the organizations that win will be those who turn their internal data into a precise, governed, and continuously refined fuel source for AI. Building that infrastructure requires intent, expertise, and the right architectural decisions made early. The race is not to the best model. It is the best data layer above it.
Ready to build an AI data pipeline that delivers real outcomes? Connect with Ksolves today or send us your query at [email protected].


 Mayank Shukla