 Airbyte
 5 MIN READ


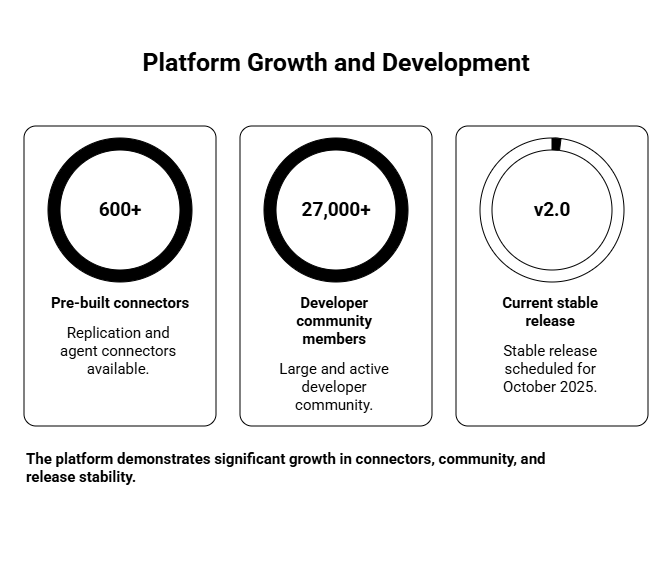
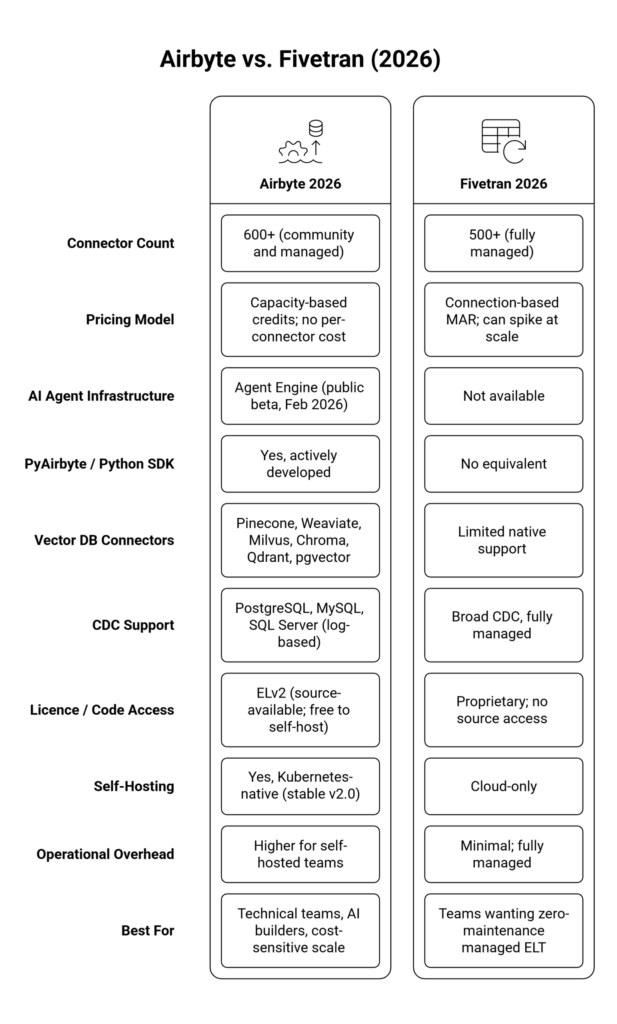
The Airbyte roadmap for 2026 signals the most significant platform expansion since the project launched in 2020. Airbyte is no longer positioning itself as a pure open-source ELT connector catalog. It is building the data infrastructure layer that AI agents need to operate reliably in production. With more than 600 connectors, a community of over 27,000 developers, and thousands of companies syncing data daily using platform version 2.1 (released April 2026), Airbyte enters the year from a strong foundation. The question is where it goes next. This post breaks down the key features Airbyte is shipping, the strategic shift from analytics ELT to AI-native data infrastructure, the accurate licensing model, and what data teams should expect across the year. We cover Agent Engine, PyAirbyte, CDC improvements, vector database integrations, and how each change affects your stack.
Why the Airbyte Roadmap for 2026 Is a Category Shift
Airbyte is not simply adding connectors in 2026. It is rearchitecting itself around a new primary use case: powering AI agents with structured, real-time access to enterprise data. Traditional analytics workflows tolerate batch processing and eventual consistency. AI agents do not. When an agent queries stale data, it produces inaccurate outputs. When it lacks permission-aware access, it risks exposing sensitive context. Traditional ELT pipelines were never designed for these requirements. Airbyte’s roadmap addresses this gap directly.
Airbyte Agent Engine: The Biggest Launch of 2026
On February 19, 2026, Airbyte launched the Agent Engine in public beta. It is a purpose-built data layer for AI agents. It gives agents structured, real-time access to enterprise systems without requiring custom integration code per source. Most AI teams spend more engineering time on integration plumbing than on agent logic. The Agent Engine eliminates that overhead.
Three Core Components at Launch
- Open-Source Agent Connectors: Python SDKs for real-time fetch, search, and write. Ten production-ready connectors launched: Salesforce, HubSpot, GitHub, Jira, Asana, Gong, Stripe, Zendesk Support, Linear, and Greenhouse. Additional alpha and beta connectors bring the total to 20-plus at launch, with new ones releasing weekly.
- Managed Authentication Module: Handles OAuth flows, token refresh, and credential storage centrally. Teams authenticate once across all connected systems. Supports per-customer credential isolation for multi-tenant applications.
- Context Store: Airbyte-managed storage that replicates and indexes a relevant subset of data from connected sources. Agents search across systems in milliseconds. Data refreshes hourly. Each source maintains its own isolated data store.
Connecting an AI agent to Salesforce through the Agent Engine takes roughly 10 lines of Python. Hundreds more agent connectors are on the roadmap, drawn from Airbyte’s existing replication ecosystem.
PyAirbyte: Open-Source ELT Inside Python Workflows
PyAirbyte lets developers run Airbyte connectors directly inside Python without deploying the full platform. Data engineers run pipeline syncs programmatically inside existing CI/CD tooling. AI developers pull data from any Airbyte connector into model training jobs, RAG pipelines, or agent workflows using Pandas, LangChain, or PydanticAI. The PyAirbyte MCP server also supports Claude Desktop, Cursor, Cline, and Warp, making pipeline management accessible through AI assistant interfaces. In 2026, PyAirbyte development focuses on tighter integration with the Agent Engine so teams manage both batch replication and real-time agent data access from a single Python interface.
For teams deciding between ELT-first and ETL-first architectures, our guide on ETL vs ELT: Key Differences and When to Use Each Approach provides a practical framework for choosing the right model for your cloud warehouse setup.
CDC Replication and Vector Database Connectors in 2026
Airbyte supports log-based CDC for PostgreSQL, MySQL, and SQL Server. In 2026, CDC feeds directly into the Agent Engine’s Context Store. When a customer updates their data in a connected CRM, CDC detects the change and streams the delta downstream within seconds. Agents get accurate context without stale-data hallucination risk.
On the AI pipeline side, Airbyte natively integrates with Pinecone, Weaviate, Milvus, Chroma, Qdrant, and PostgreSQL with pgvector. The platform handles automatic chunking, embedding generation, and metadata extraction before loading into vector destinations. This makes Airbyte a practical choice for teams building retrieval-augmented generation systems without a separate preprocessing pipeline. The AI-powered Connector Builder also uses LLMs to generate new connectors from API documentation in minutes, making Airbyte one of the best open-source ELT tools for AI pipelines in 2026.
Teams building AI pipelines on top of a full data stack can read our overview of Top Data Engineering Services for Big Data Pipelines to see how ELT, streaming, and vector storage fit together in production.
Airbyte vs Fivetran in 2026: Platform Comparison
Why Ksolves for Airbyte-Powered Data Pipeline Implementation
Deploying an open-source ELT platform like Airbyte delivers full value only inside a well-designed data architecture. At Ksolves, our Big Data engineering practice covers ingestion design, ELT development, Apache Airflow orchestration, cloud warehouse integration across Snowflake, BigQuery, and Redshift, real-time streaming with Kafka and Flink, and data quality frameworks. Our team also supports Apache NiFi deployments through the Data Flow Manager product.
As Airbyte’s 2026 roadmap expands into AI agent infrastructure, the implementation decisions become more involved: choosing between replication and agent connectors, configuring the Context Store, planning the Helm chart V2 migration from v2.0, and deciding when PyAirbyte fits better than the full platform. Ksolves brings over 11 years of big data engineering experience and applies AI-assisted project dashboards and code review tools to surface risks earlier in the delivery cycle. This delivers fewer revision cycles, faster time-to-production, and solutions built to scale. If your team is evaluating Airbyte as part of a modern data stack or AI pipeline initiative, start with a scoped architecture review.
Conclusion
The 2026 roadmap for Airbyte is technically credible and strategically coherent. The platform is building a new infrastructure layer that serves both batch analytics ELT pipelines and real-time AI agent workflows from a single source-available codebase licensed under ELv2. Agent Engine, PyAirbyte, CDC improvements, and deep vector database integrations all point toward a platform positioned as the data layer for production AI applications alongside traditional analytics. For data teams that value flexibility, cost control, and the ability to inspect and modify integration code, Airbyte remains the strongest open-source ELT choice in 2026. The stable v2.0 release gives teams a solid foundation, while the experimental v2.1 signals where the platform is heading. To explore how Ksolves can help implement Airbyte effectively as part of your data stack, contact our team at [email protected].


 Anil Kushwaha